An open lakehouse, ready on day one
Dataspheres brings your sources into Delta tables on your own Azure storage and organizes them in a governed catalog. You query everything with SQL, with no cluster to assemble or maintain.
- Fivetran
- Delta Lake
- Azure Data Lake Storage Gen2
- Unity Catalog
- Spark and Kyuubi
What you get
Managed ingestion
Fivetran connectors bring databases and SaaS applications into the lakehouse on a schedule. File uploads go to a volume and become catalog tables.
- Ingested tables are registered in the catalog automatically
- Ingested data is read-only, so no one overwrites a source by accident
- Removing a connector stops the sync and keeps the data
Analytical layers from the start
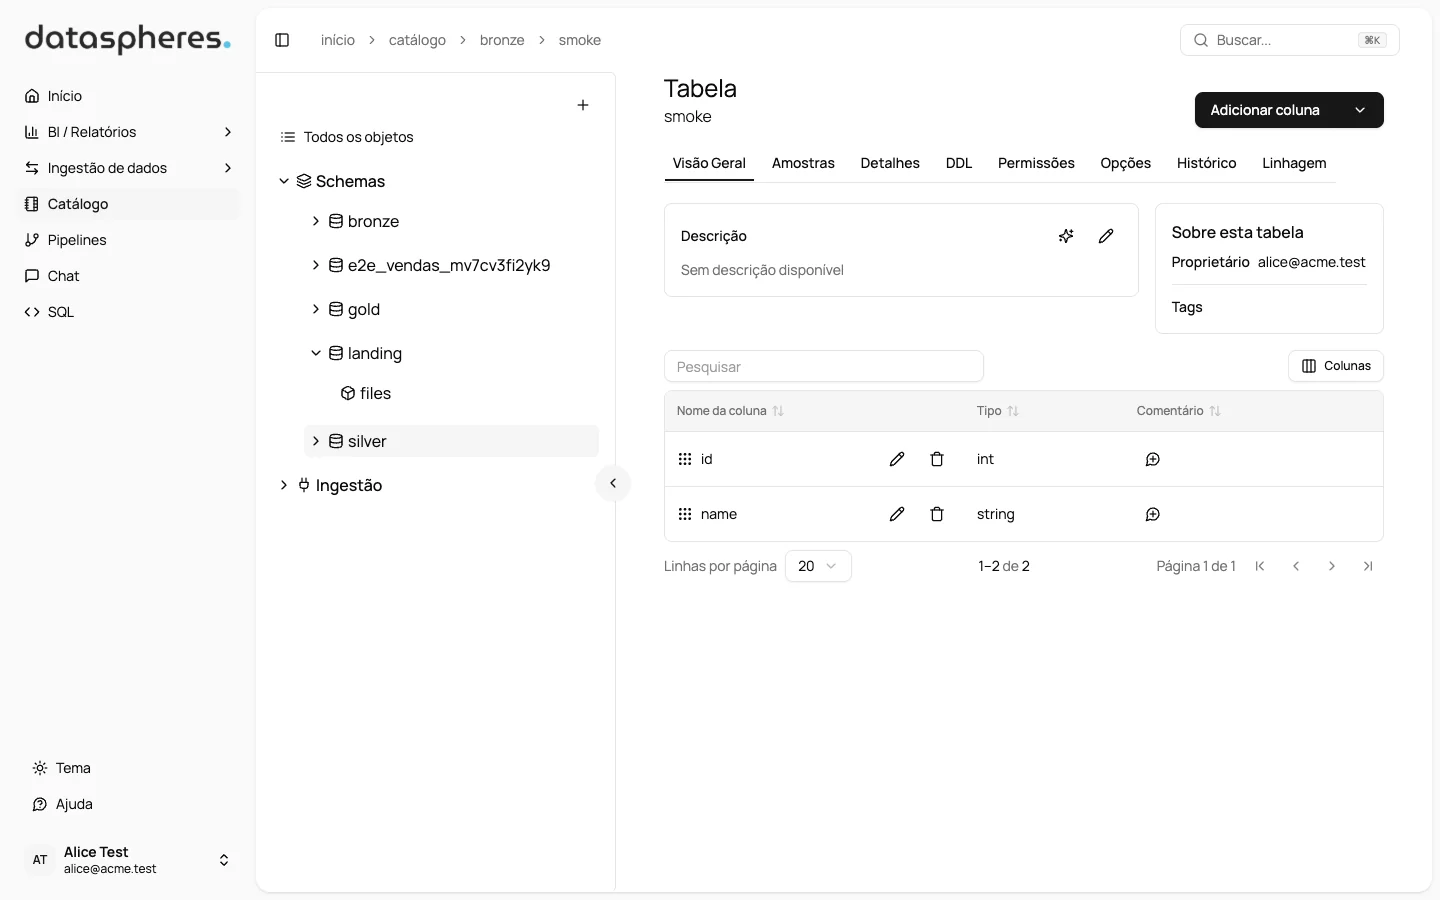
Every workspace starts with bronze, silver and gold schemas. Your team creates new schemas as the model grows.
- Write access granted per schema
- Same layout for every team in the company
- Raw, cleaned and curated data kept apart
Open format on your storage
Tables are Delta Lake files in Azure Data Lake Storage Gen2. Your data stays in an open format that other tools can read.
- No proprietary storage format
- Each company has its own storage prefix
- Dropping a table also removes its files
Distributed SQL
Queries run on Spark 4 through Kyuubi, with the permissions of the user who wrote them.
- CREATE TABLE AS SELECT over the whole lakehouse
- One engine per user, isolated from the others
- Results in the SQL editor, in dashboards and in the AI chat
See Dataspheres with your own data
Book a demo and we will walk you through the whole path, from source to chat.